One Year, 24 Posts: What Held Up and What Didn't
My first post promised a revolution. My recent ones mostly report what failed. A plain-language look back at a year of writing about data tools, written for readers who have never used any of them.
My first post promised a revolution. My recent ones mostly report what failed. A plain-language look back at a year of writing about data tools, written for readers who have never used any of them.
My data profiler gives the same untouched file a lower score on New Year’s Day. I found that by using it as a dependency for the first time. On the glue a real pipeline needs, and the line between what a library should do and what it should leave to the caller.
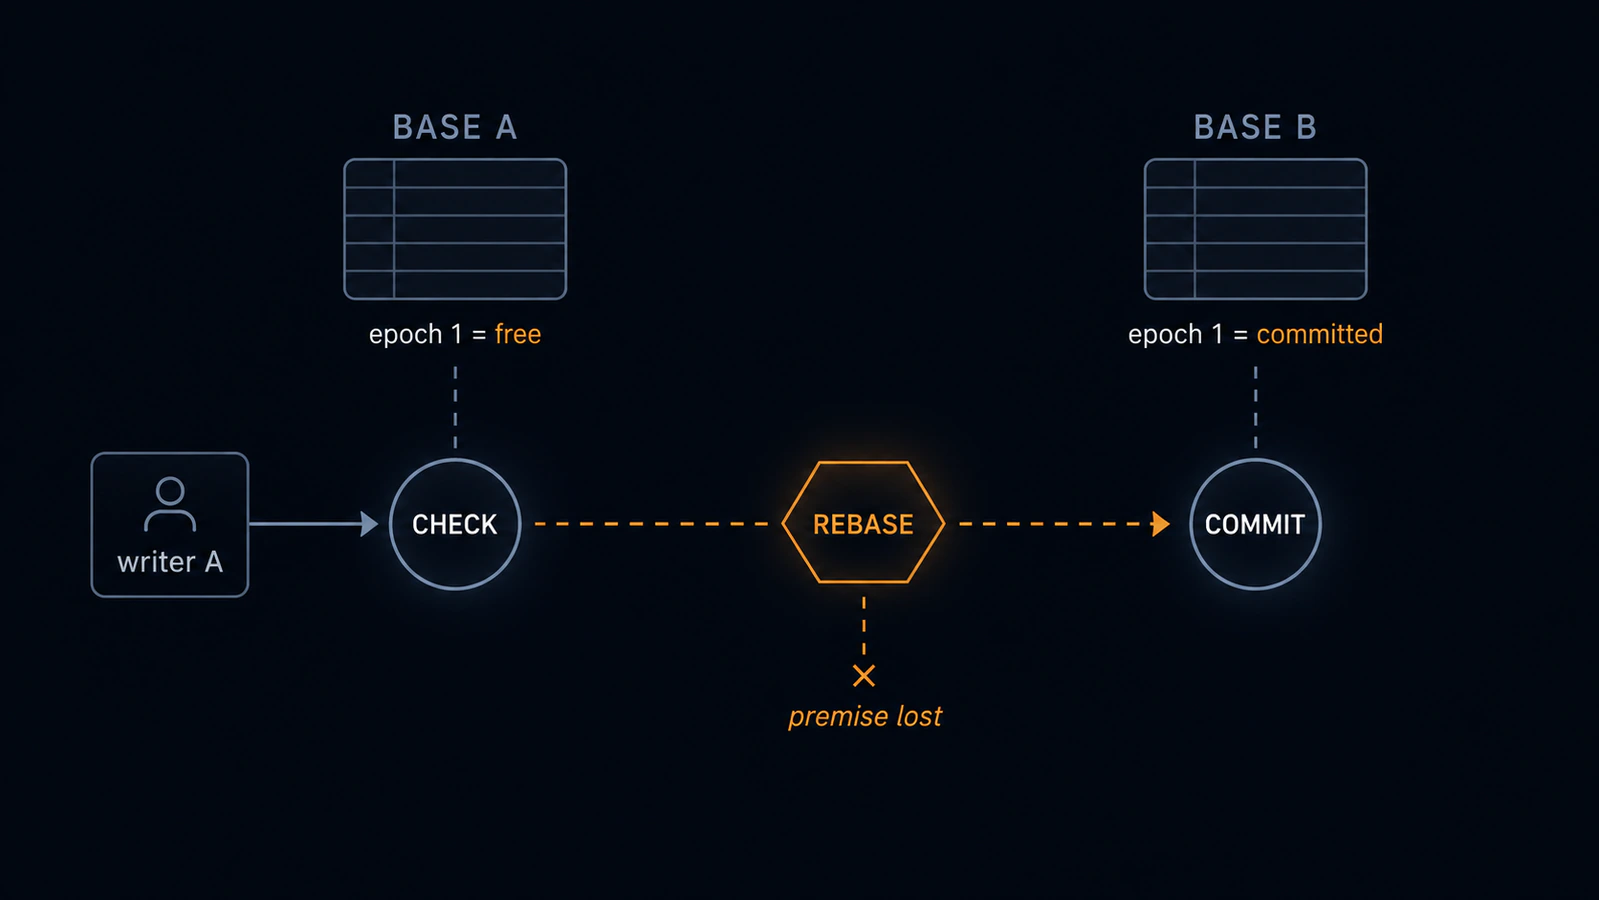
A falsification experiment with a written kill list and a negative result. Delta has a purpose-built idempotent commit; iceberg-rust rebases a transaction onto a base the caller never checked, so an external writer cannot make a commit conditional. The green concurrency test was a false pass — 0 of 40 rounds ever raced — and only a failpoint showed the duplicate.
I started with Milan in Championship Manager 03/04, went through an almost perfect auction and a season shaped by injuries, then built Fantabuddy on holiday: a system that turns player lists, history and APIs into an auditable auction report.
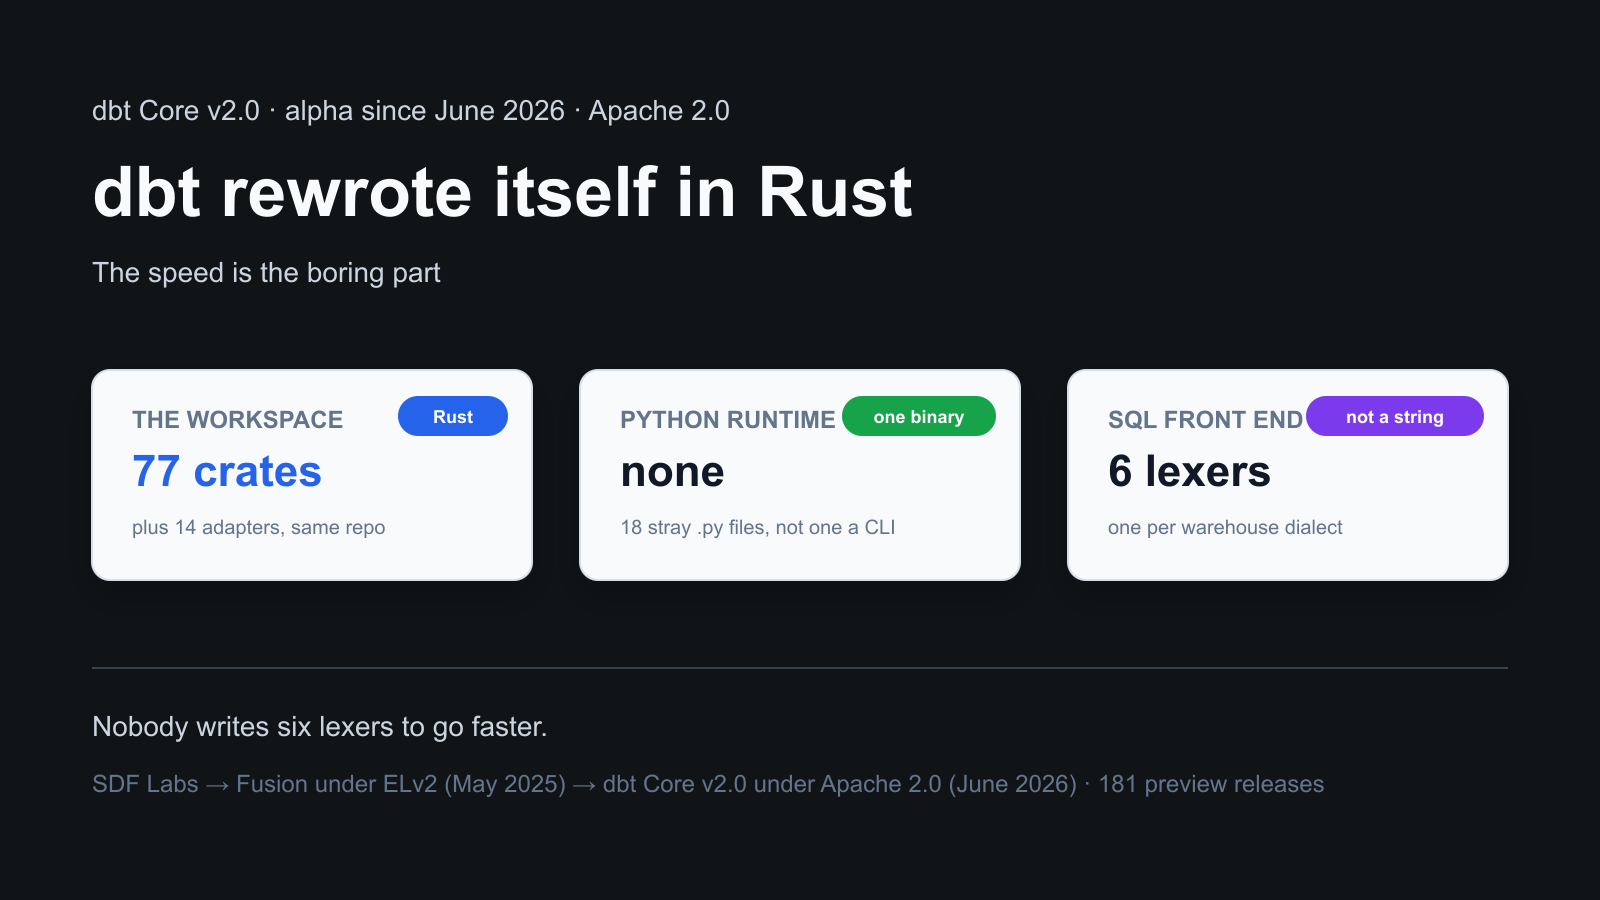
I opened a bug report against dbt and found a codebase nobody had told me about: 77 Rust crates where the Python used to be. This is what the rewrite is actually for, why the marketing undersells it, and what I broke loose while poking at it — two fixes, both for bugs that never printed an error.
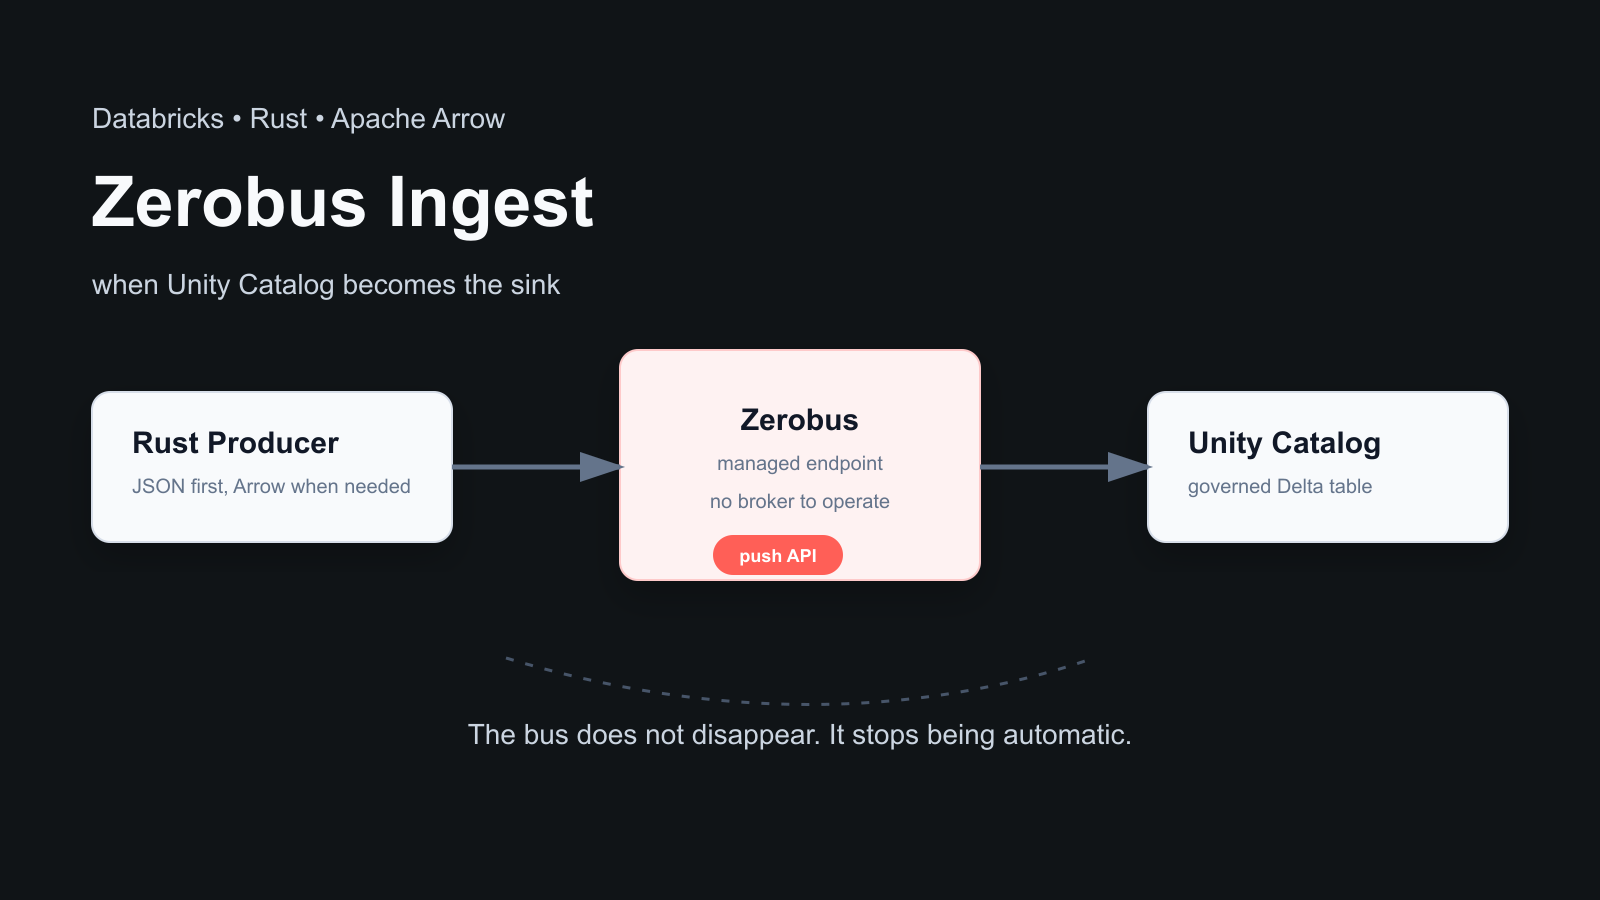
In the dlt+dbt post the contract was a Unity Catalog schema. With Zerobus Ingest I moved the same question to the producer edge: when the sink is already a governed Delta table, do you really need a bus in the middle?
Python-native ingestion with dlt (dlthub), SQL transformation with dbt, and a single Unity Catalog schema as the contract between them. Notes from wiring them together on a real Databricks workspace — including the naming collision that bit me in actual code.
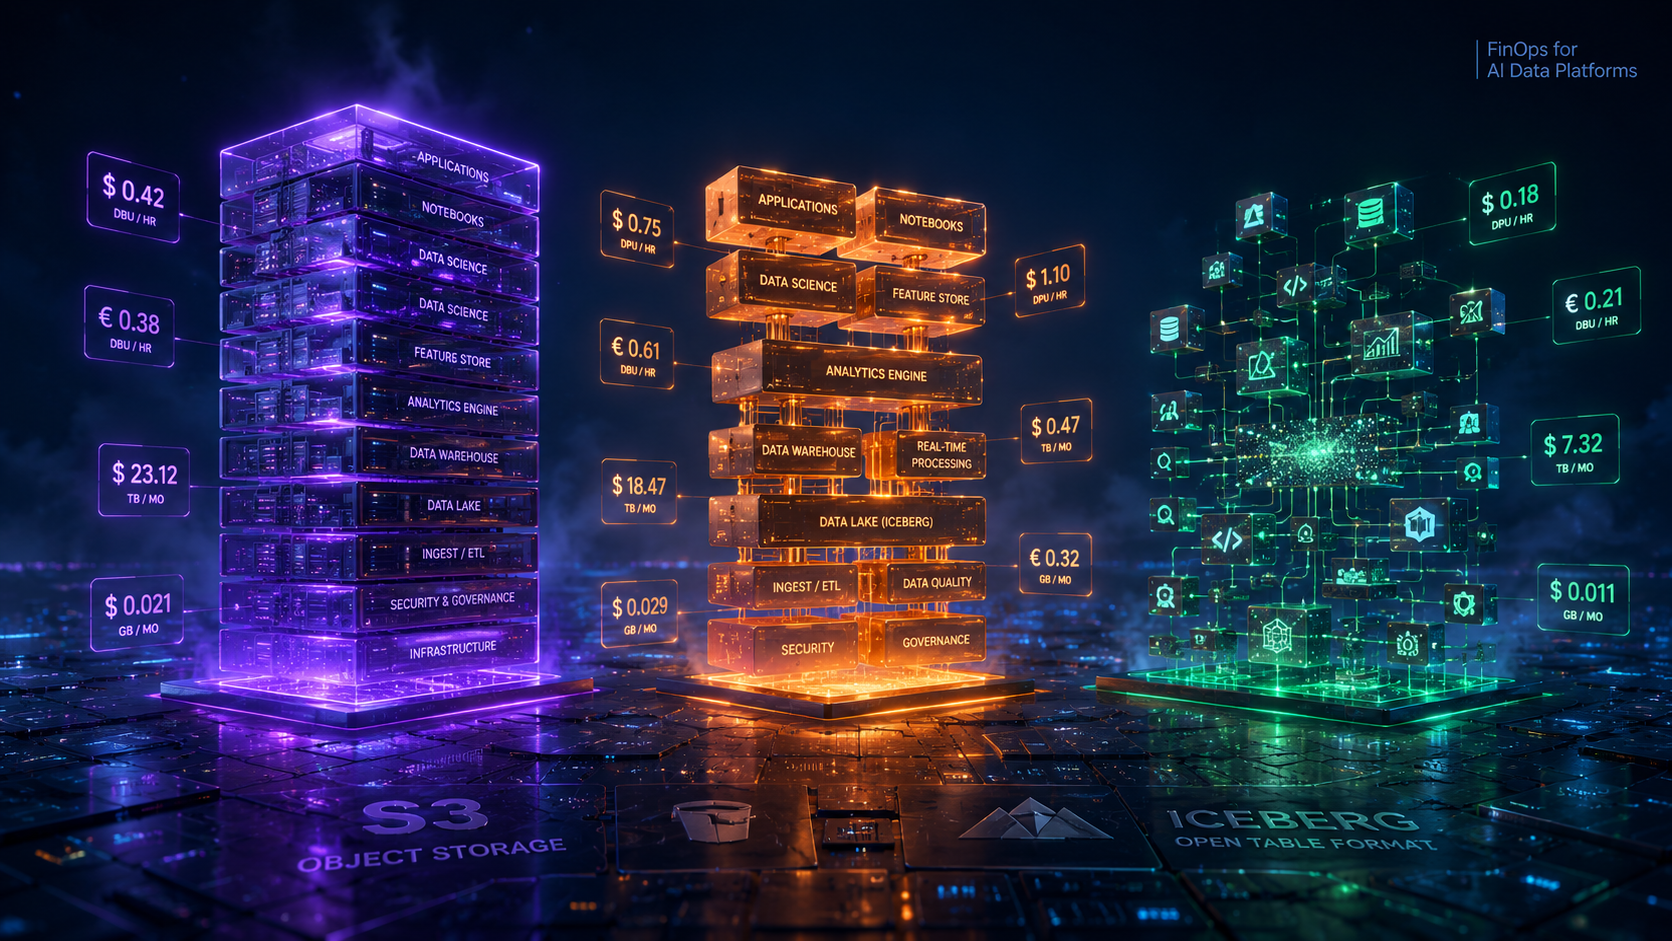
Three lakehouse stacks for adding AI/ML and streaming on top of an existing warehouse, compared through a FinOps lens: DBUs, DPUs, TB-scanned, S3 GB-month, and egress, walked through real workload patterns with 2026 prices.
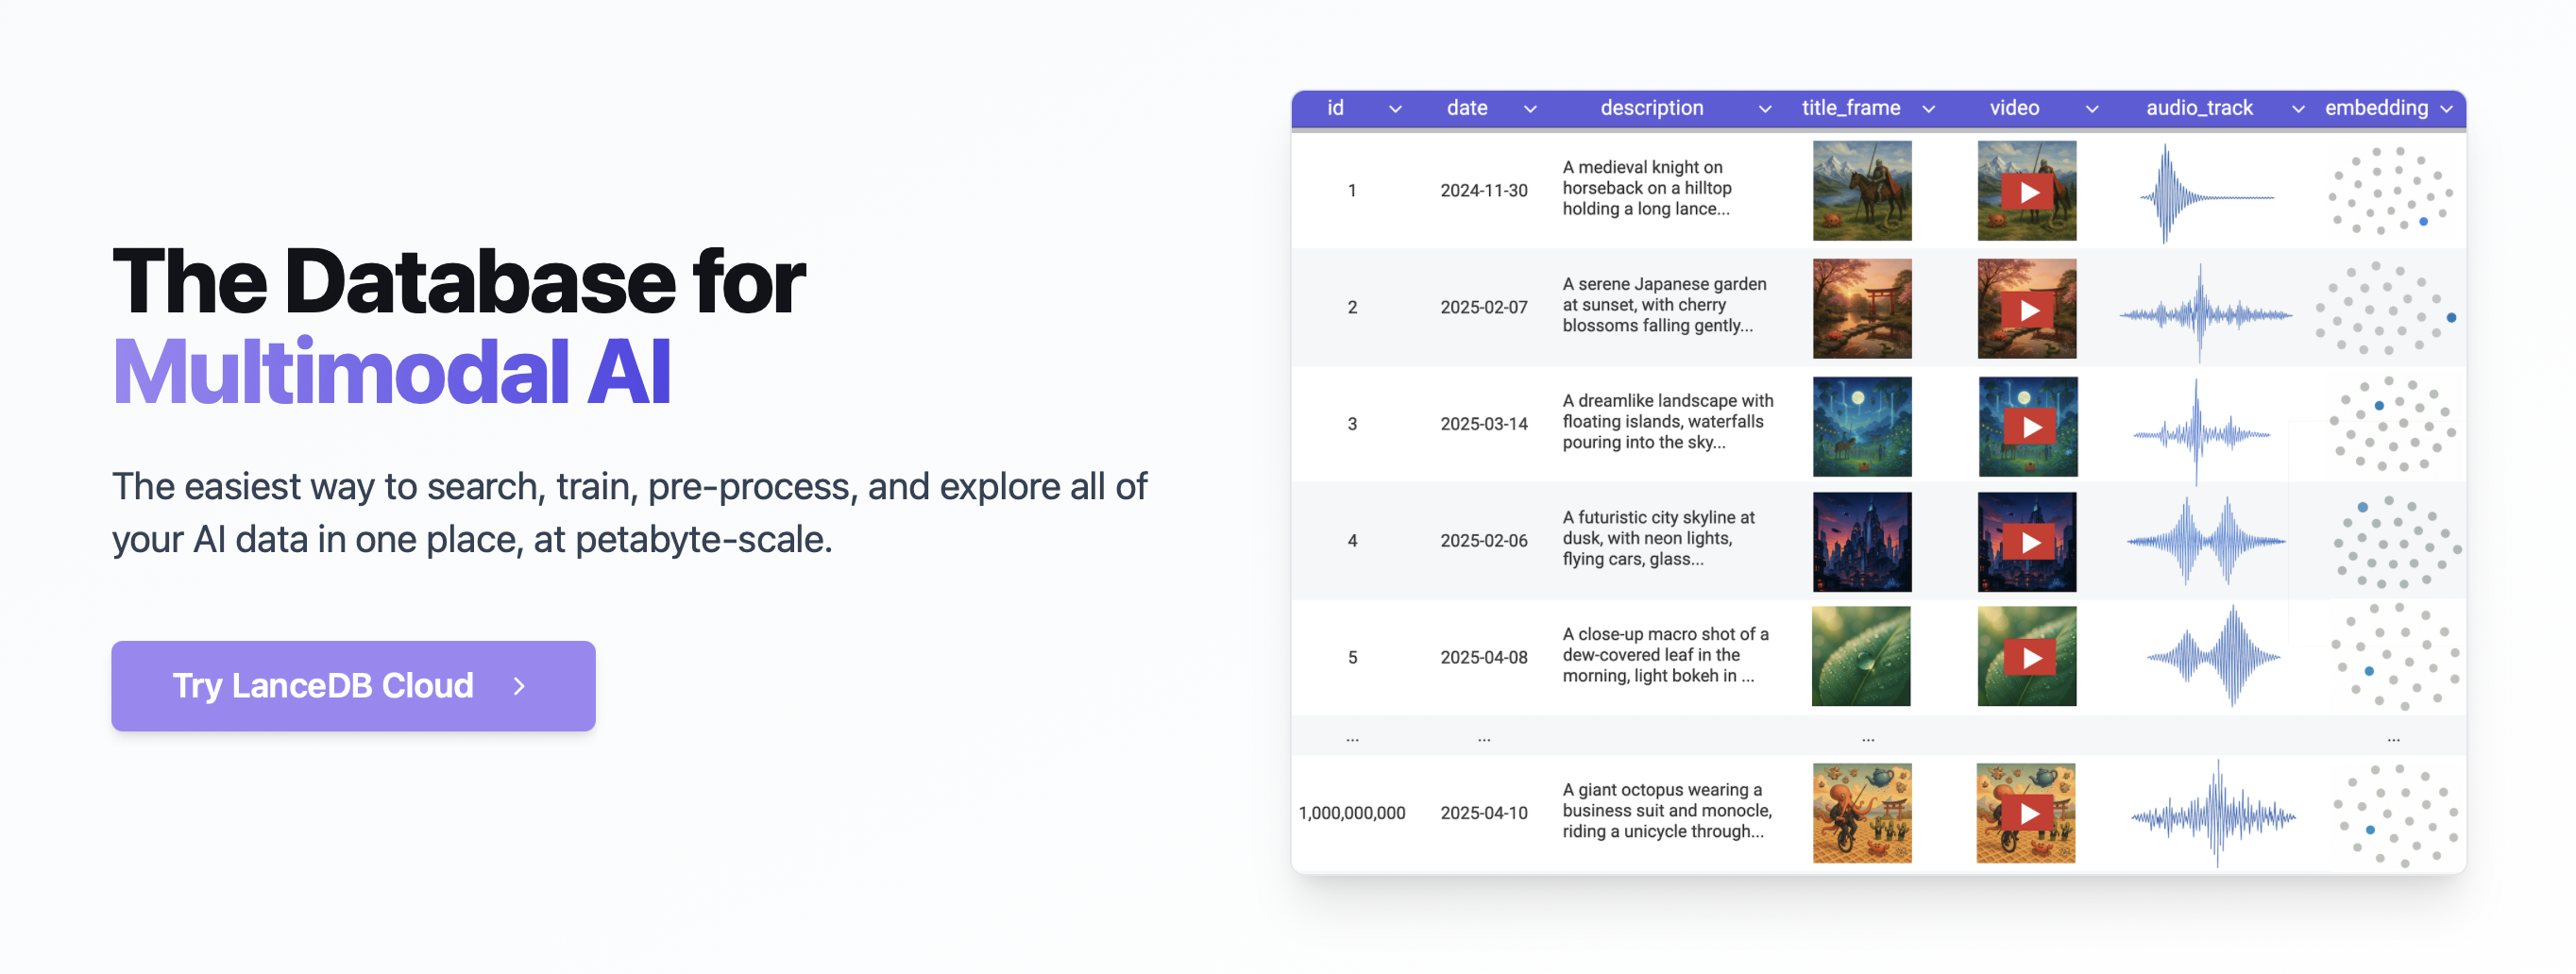
Lance is a columnar storage format built for machine learning workloads — fast random access, native vector indexing, and zero-copy Arrow integration. This article walks through the format itself, how LanceDB builds on top of it, and how I wired it into a live NATS stream to build a simple semantic search layer over real-time events.
Most ML pipeline failures are not exotic model bugs — they are data issues that nobody encoded as checks. This article walks through building guardrails using pandas, Apache DataFusion, data contracts, and the Arrow C Data Interface.